
Conditional independence describes the situation where correlations between two variables A and C can be explained entirely through the value of a third variable B. We then say that A and C are conditionally independent given B.
In our work, we study how efficiently this property can be tested when the joint distribution is unknown, and we can only access the distribution via independent samples. The goal is to perform this test using as few samples as possible.
We quantify correlations between random variables using the mutual information, defined as , and conditional correlations using the conditional mutual information . For independence testing, the task is then to decide whether or . In the case of conditional independence, we ask whether or if . A related problem has previously been studied by Canonne, Diakonikolas, Kane, and Stewart (STOC 2018), where the farness guarantee was expressed using the so-called total variation distance instead of the conditional mutual information. This algorithm might be applied to our problem of (conditional) mutual information testing, however it is not sample optimal for this task.
The idea behind our algorithm is to reduce the problem to instances of equivalence testing, that is, testing whether two unknown distributions are equal or not. In our case, this means we need to simulate samples from to compare it to . The test uses a reduction to -distance testing, pioneered by Diakonikolas and Kane (FOCS 2016), in which the domain is partitioned into subsets , based on the weight of . This allows us to tightly link guarantees in the -distance to the conditional mutual information. The subsets are then tested separately. Our partitioning is tailored to also take the specific structure of into account, to be even more efficient than general equivalence testing.
Simulating , and handling the resulting algorithmic implications, are the key technical challenges of our work. When is large,the available data contain sufficiently many samples with B=b, making it relatively straightforward to simulate independent draws from and . For values of with small , however, there may not be enough such samples. We therefore simulate only approximately in this regime. The resulting samples are both biased and correlated, requiring a different analysis and giving rise to several regimes in the final sample complexity. The sample-complexity upper bounds of our algorithm and that of Canonne et al. are shown below, up to polylogarithmic factors.
The sizes of the subsystems are given by , , and , respectively. We assume without loss of generality that . The parameter denotes the farness guarantee in conditional mutual information and denotes the corresponding guarantee in the total variation distance problem.
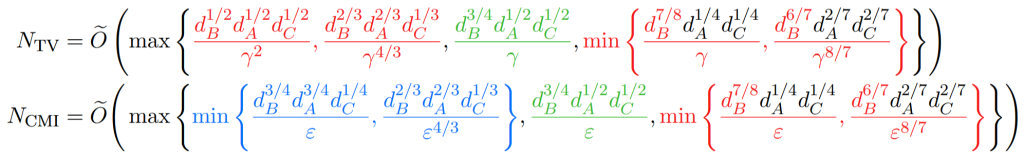
The lower bounds on the sample complexity are shown in color (red: derived by Canonne et al., blue by Seyfried et al., green: by Canonne et al. for the special case , constant). These bounds already proved that the observed structure is right – the five different regimes and nested case distinctions are necessary. However, the exact form of certain terms was not fully resolved. This left open whether a different tester could improve on the simulation-based reduction to -testing in this regime.
In our follow-up work, we showed that the sample complexities derived by Canonne et al. for conditional independence testing and Seyfried et al. for conditional mutual information testing are indeed optimal, up to logarithmic factors. Our proof is based on generalizing the constructions by Canonne et al., which did not fully resolve all regimes.
For further details, please see Seyfried, Sen, and Tomamichel (COLT 2025) for our algorithm to test conditional mutual information, and Seyfried, Mishra, Sen, and Tomamichel (COLT 2026) for the aforementioned lower bounds.